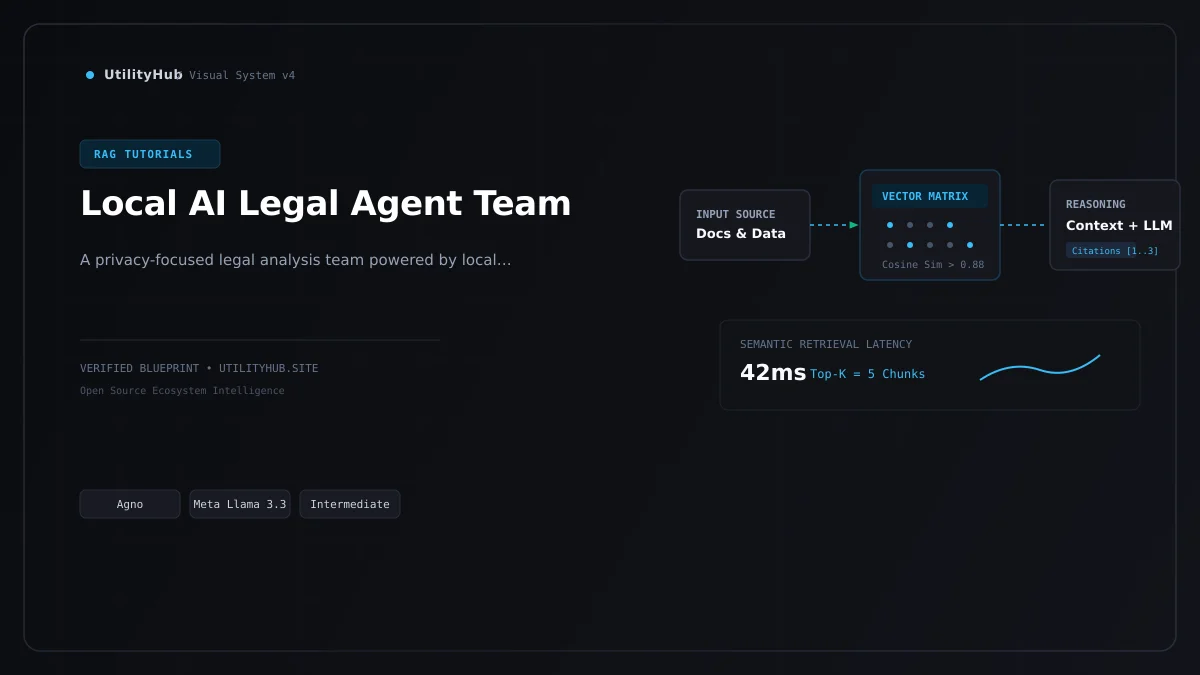
Local AI Legal Agent Team
A privacy-focused legal analysis team powered by local Ollama models, Agno, and Qdrant vector search to analyze contracts and legal documents offline.
At a Glance Specifications
01 // What It Does
This blueprint illustrates how to construct a robust hybrid retrieval augmented generation (rag) utilizing Agno. It showcases clean separation between user input handling, LLM prompt formatting, external tool execution, and response synthesis.
02 // How It Works & Architecture
The architecture leverages Agno to manage conversation state while isolating API calls and tool definitions. This prevents context bloat and ensures predictable execution paths during multi-step reasoning cycles.
03 // Real-World Use Cases
- • Building internal developer tools and automation agents for enterprise document search & q&a.
- • Serving as an architectural reference for enterprise workflows requiring reliable tool calling.
- • Prototyping next-generation AI applications with minimal operational dependencies.
Technical Boundaries
Relies on upstream LLM API uptime and latency. Requires careful token budget management for long conversational contexts and sandboxing for untrusted external tool executions.
Production Considerations
For production deployment: introduce persistent session storage (e.g., Redis or PostgreSQL), implement strict rate limiting and request timeouts, add OpenTelemetry tracing for agent observability, and enforce granular RBAC for all executed tools.
Need this deployed or customized for your business? UtilityHub Engineering can help.
From private LLM orchestration and custom tool connectors to security audits, observability, and dedicated cloud hosting — get production-ready support for Local AI Legal Agent Team.
Why This Project Matters
As AI systems evolve from passive text generators into active decision-making agents, understanding how to cleanly wire tool calling, retrieval, and state management in Agno is critical for engineering reliable software.
Quickstart Setup Guide
# 1. Clone the upstream repository
git clone https://github.com/Shubhamsaboo/awesome-llm-apps.git

# 2. Enter this blueprint directory
cd awesome-llm-apps/advanced_ai_agents/multi_agent_apps/agent_teams/ai_legal_agent_team/local_ai_legal_agent_team

# 3. Create and activate a Python virtual environment
python3 -m venv venv
source venv/bin/activate  # Windows: venv\Scripts\activate

# 4. Install dependencies
pip install -r requirements.txt

# 5. Export required API keys in your environment
export OPENAI_API_KEY="your-api-key"

# 6. Execute application entrypoint